Notes from the lab
Benchmarks, build notes and research on agents, retrieval and reinforcement learning, from Trilogy's AI Center of Excellence.
-
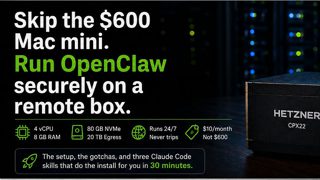
Skip the $600 Mac mini. Run OpenClaw securely on a remote box.
The setup, the gotchas, and three Claude Code skills that do the install for you.
“An assistant that does not stop when you close your laptop lid.”
↗ -
Building the AI COE Chatbot
Willfully over-engineering a simple RAG bot to explore agentic workflows.
“Latency is the king of chat.”
↗ -
Reinforcement Learning for Agents, Part II
Agent Lightning, Handit.ai, and a homegrown tool, AgentEvolve.
“There’s a glaring gap in this space.”
↗ -
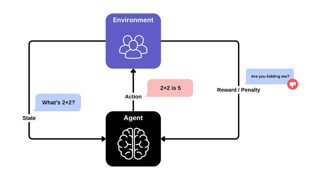
Reinforcement Learning Techniques to Optimize Agents
Can RL loops continuously refine prompts, tools, and agentic pipelines?
“You’re not merely tuning weights. You’re actually trying to improve the source code.”
↗ -
Auto-Improve Bitcoin Algo Trading Strategies with LLMs
Building and auto-refining algorithms with multi-model LLM loops.
“From a negative -2.06 sharpe to a +3.99 sharpe.”
↗ -
Agentic Automation for Social Content
Content creation, approval and scheduling with n8n and Airtable.
“Tool sprawl is killing productivity.”
↗ -
Analyzing Large Datasets with LLMs
Taming context limits and building reasoning agents for enterprise-scale insight.
“LLMs are great with words, but weak with math and worse with scale.”
↗ -
The Hidden Cost of Scattered AI Tooling
And a four-layer framework for scalable enterprise adoption.
“The rush toward AI everywhere often swaps one kind of debt for another.”
↗ -
Claude Code: Triumphs, Trials and Trade-Offs
Its architecture, standout features, and where it still falls short.
“Incredibly smart and inexplicably dumb at the same time.”
↗ -
Agentic Retrieval Deepdive
A benchmarking study of off-the-shelf and custom agentic retrieval pipelines.
“None of the advanced setups outperformed a strong dense baseline.”
↗ -
Retrieval Benchmarking: Agentic vs. Vanilla
Which datastores and embeddings actually win on retrieval accuracy.
“Out-of-the-box agentic solutions consistently underperform vanilla retrieval.”
↗